
Every ambitious idea in orbital industry — debris capture, satellite servicing, in-space manufacturing, asteroid prospecting — runs into the same wall: a human with a joystick cannot do the job. Light takes about a quarter of a second to make the round trip to geostationary orbit and back. To Mars, the one-way delay ranges from roughly 4 to 24 minutes depending on where the planets sit. A robotic arm reaching for a tumbling satellite, or a rover threading a boulder field, cannot wait for permission from a control room on Earth. The machine has to perceive, decide, and act on its own.
We treat AI and robotics as an enabling discipline across our long-term research areas. Our current foundation is ground-based: private GPU compute, an air-gapped development environment, reinforcement-learning research, and robotics experimentation. We distinguish those capabilities from the embedded and spaceflight systems we may pursue later.
Ground-first autonomy research
Our immediate work is concerned with questions we can test on the ground: how a controller handles uncertain observations, how a model behaves outside its training distribution, and how a system reports or contains failures.
Simulation, repeatable evaluation, and physical experiments provide different kinds of evidence. We treat them as complementary steps, not interchangeable demonstrations of flight readiness.
 Deep reinforcement learning trains control policies through millions of simulated trials — an approach we run on our own GPU cluster today.
Learning to fly: reinforcement learning for spacecraft control
Classical spacecraft control is built on precise models and pre-planned sequences. That works beautifully when the world cooperates. It breaks down when the target is a dead satellite tumbling unpredictably, a landing site turns out rockier than the maps showed, or a thruster underperforms mid-maneuver.
Deep reinforcement learning offers a different path. Instead of hand-coding every contingency, an agent learns a control policy by trial and error across millions of simulated episodes — approaching a tumbling object, docking under sensor noise, guiding a powered descent — and is rewarded for outcomes rather than for following a script. This is an active and serious research field: published work from universities and industry labs has demonstrated learned policies for six-degree-of-freedom docking, planetary landing guidance, and constellation management in high-fidelity simulation, and learned components are beginning to appear alongside classical guidance in flight-software research. Those are the field’s published results, not experiments SDI has performed.
The hard problem is the one the field calls sim-to-real transfer: a policy that is superhuman in simulation must survive contact with reality, where dynamics, lighting, and sensor behavior never quite match the training environment. The standard tools — domain randomization, high-fidelity physics, hardware-in-the-loop testing, and runtime safety monitors that bound what the learned policy is allowed to do — are exactly the kind of patient, ground-based engineering that can be done without a launch. That is where our reinforcement learning research lives today: training and evaluating control policies on our own cluster, in simulation environments we control end to end, with our ground robotics testbed as the physical proving ground. Our own experiments to date are simulation training runs and ground-robot trials, not spacecraft. Verification and validation of learned systems — proving to a mission assurance board that a neural network will behave — is, in our view, as important a research problem as the learning itself, and we treat it that way.
Local compute today; constrained deployment as a research direction
Our present computing foundation is a private GPU cluster, including an air-gapped environment for local AI development and inference. It supports model evaluation, performance measurement, and reproducible experiments without relying on cloud inference.
Smaller robotic and onboard systems present a separate deployment problem: power, memory, latency, fault handling, and verification must be evaluated for the target platform. Those constraints inform our research direction; they are not capabilities established merely by operating a ground-based cluster.
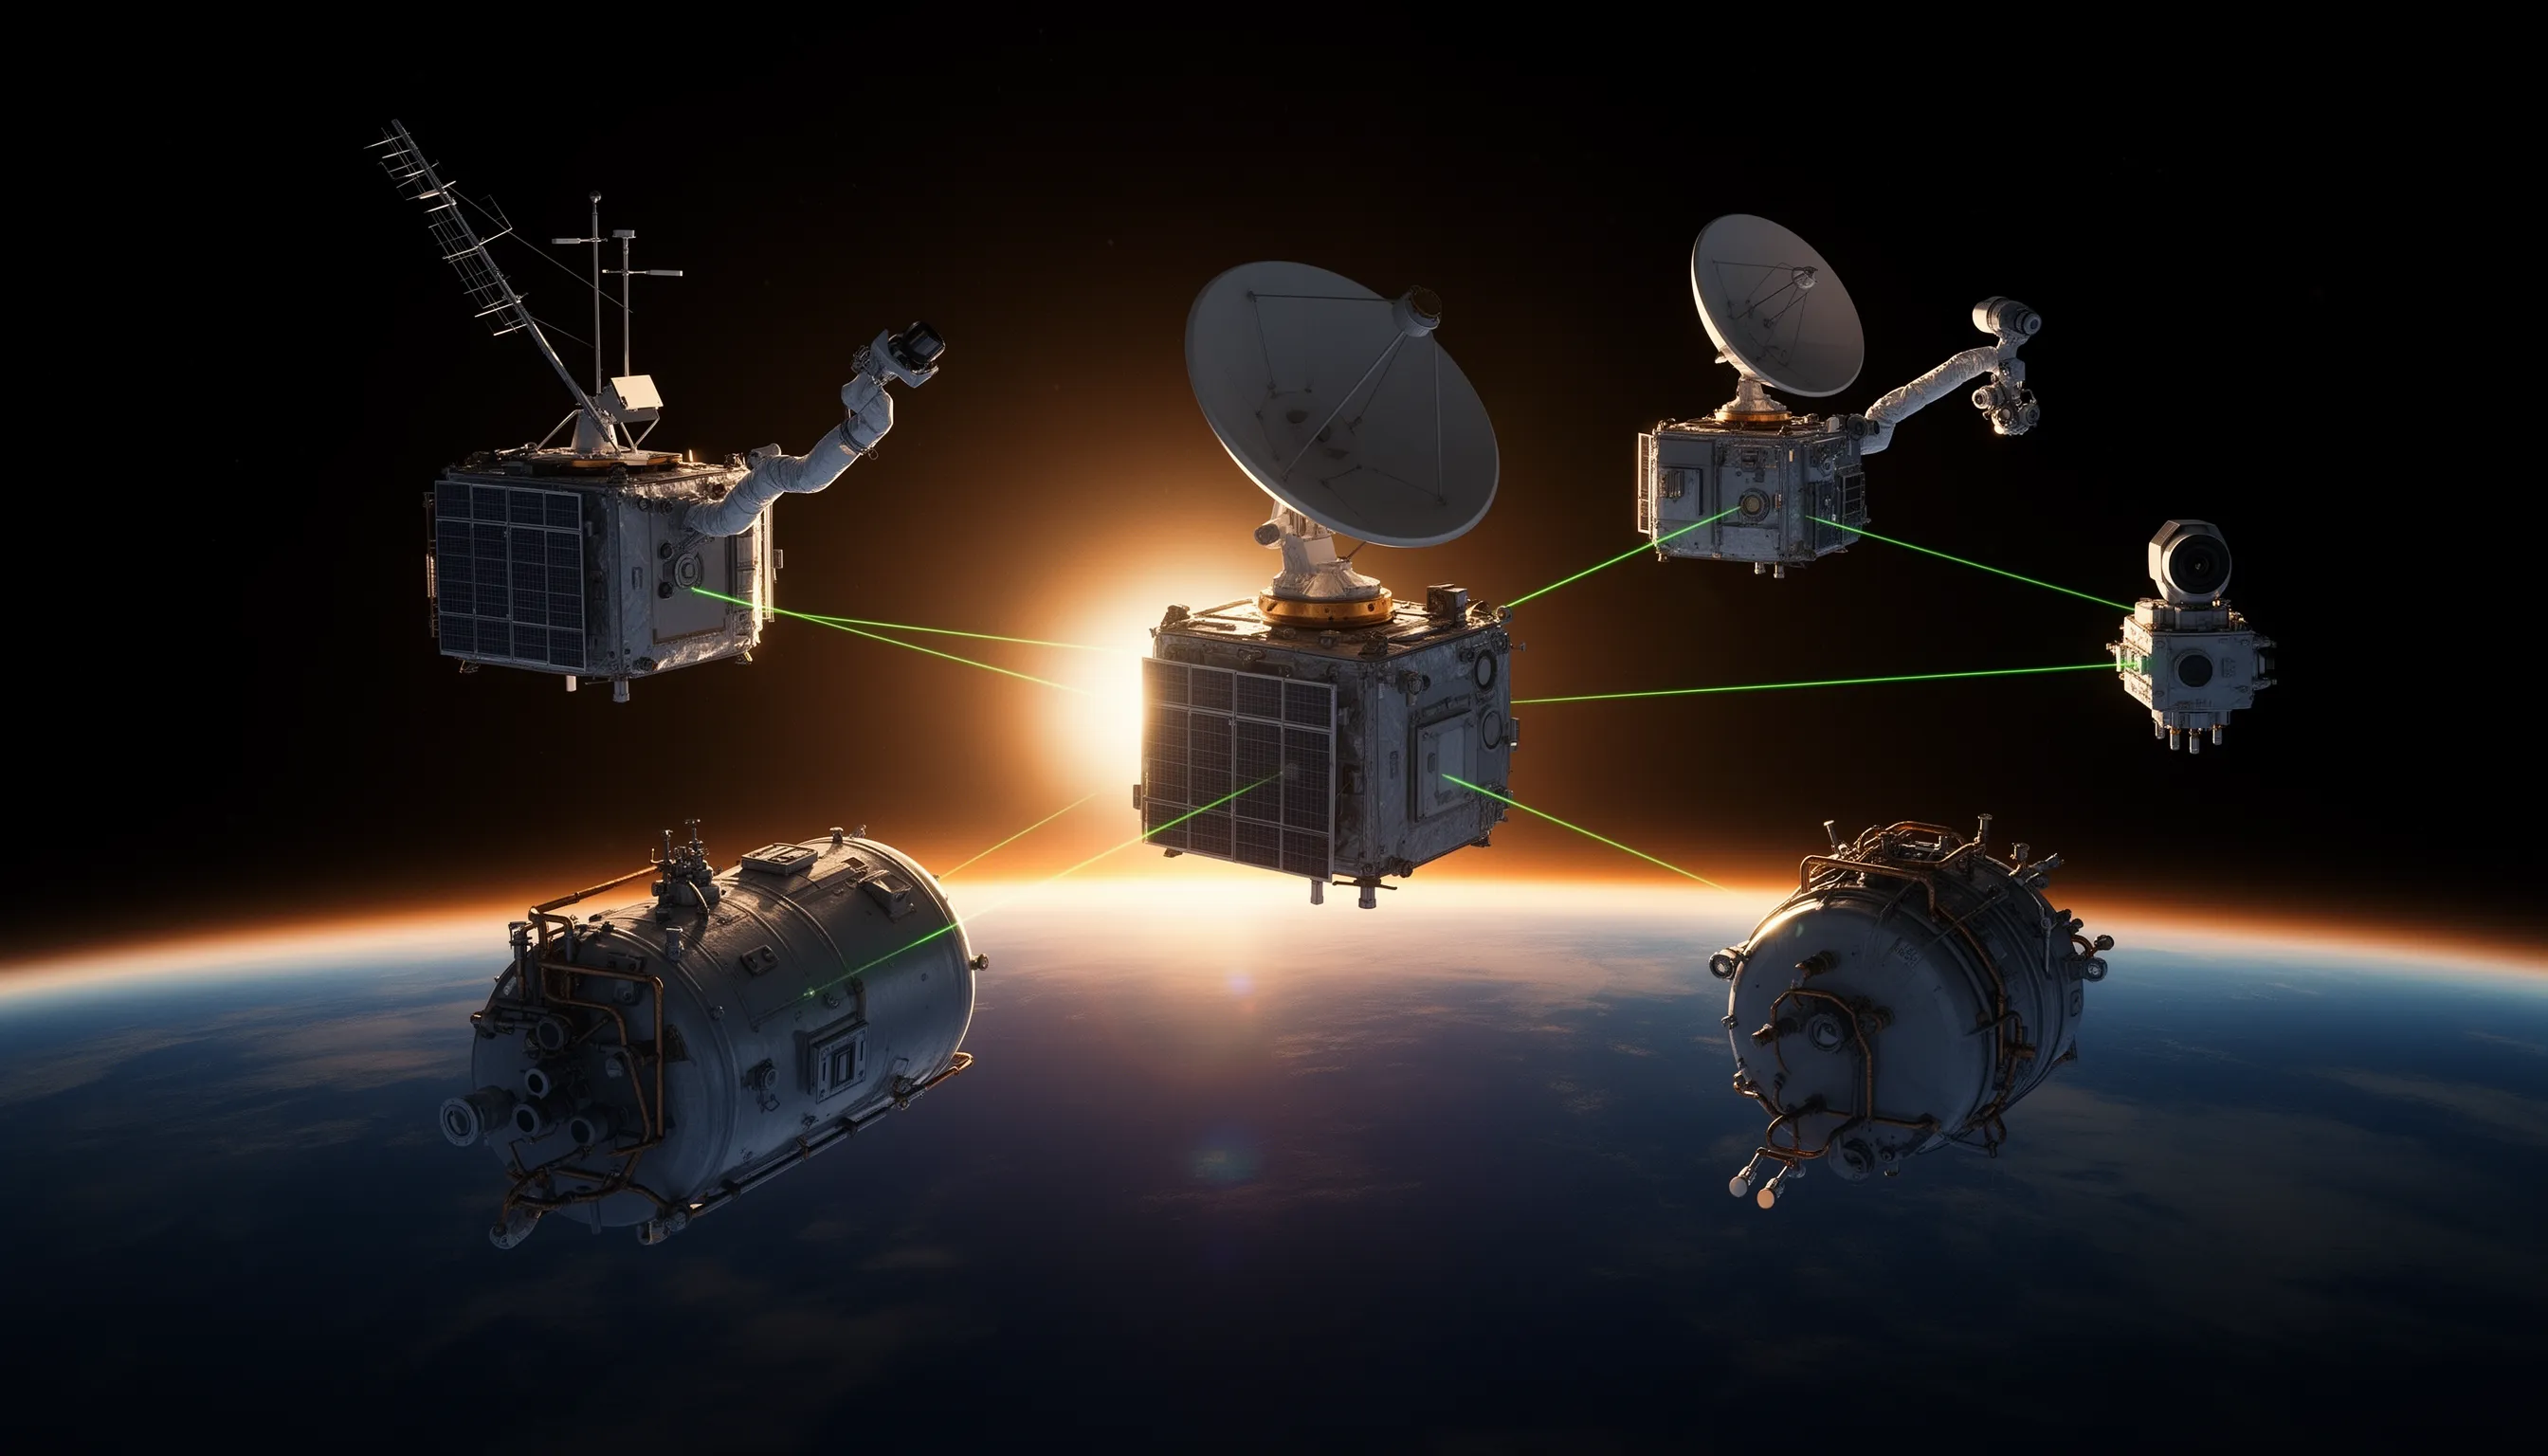 Multi-agent research asks how fleets of spacecraft can divide work, share findings, and tolerate the loss of individual members.
From one robot to many
The next leap after single-spacecraft autonomy is coordination. Large constellations already demand it — operators managing thousands of satellites rely on automated collision-avoidance and stationkeeping because no human team can hand-fly that many vehicles. Research is pushing further, toward true multi-agent systems: swarms of small spacecraft that map an asteroid from many angles at once, distributed telescopes that synthesize a single large aperture, and servicing fleets where inspection, capture, and refueling are handled by different specialized vehicles.
The interesting problems are decentralized by nature. Agents must reach consensus on a plan over intermittent, delayed links; reassign roles when a member fails; and share what they learn without flooding the network. Multi-agent reinforcement learning and classical distributed algorithms both contribute, and the frontier is combining them into systems that are provably safe. Our own multi-agent research runs on the ground — coordinating simulated fleets, and the agentic AI systems we build for terrestrial work, where multiple autonomous software agents plan, delegate, and verify each other’s output. The architecture questions are strikingly similar whether the agents are processes in a cluster or spacecraft in a formation. We consider that work relevant groundwork for this mission area — groundwork, not a demonstrated spacecraft fleet controller.
Research directions: planning and navigation
Our longer-term interests include planning under changing constraints and perception-driven navigation. We are interested in systems that make assumptions explicit, expose uncertainty, and retain appropriate human authority over consequential decisions.
These are research directions, not claims of deployed spacecraft capability. Specific SDI implementations and demonstrations will be identified separately as they mature.
Our earlier concept studies also sketched the destinations this autonomy serves — orbital transfer and servicing stations that act as logistics hubs, autonomous prospecting spacecraft with AI-driven spectral analysis for asteroid surveys, and long-duration probes for environments too distant or hostile for teleoperation. These remain concepts, and we present them as such. What makes them worth sketching is that every one of them is gated on the same technology: robots that can be trusted to work alone.
The Road Ahead
Our immediate platform is on the ground: local GPU compute, independently developed software, robotics experiments, and digital manufacturing. We use that platform to investigate autonomy problems that can be measured and tested today. The orbital applications remain the long-term direction — not a claim of flight heritage. Intelligence first. Then orbit.